 Skip to content

Adaptive Flushing in MariaDB controls how fast I Dirty Pages write from the buffer pool to the disk so that the redo log never becomes a bottleneck. When I optimize MariaDB Adaptive Flushing, latency spikes decrease, and the Checkpoint-Progress remains steady, and the write load remains predictable.
Key points
- Measured values First: Redo log level, dirty page percentage, checkpoint age
- I/O capacity Determine the actual value, not an estimate
- Threshold values Set appropriately: adaptive_flushing_lwm and Dirty-Page-LWM
- Background I/O Set the following values: io_capacity and io_capacity_max
- Redo Logs Size appropriately to ensure uniform flow
How Adaptive Flushing Works in MariaDB
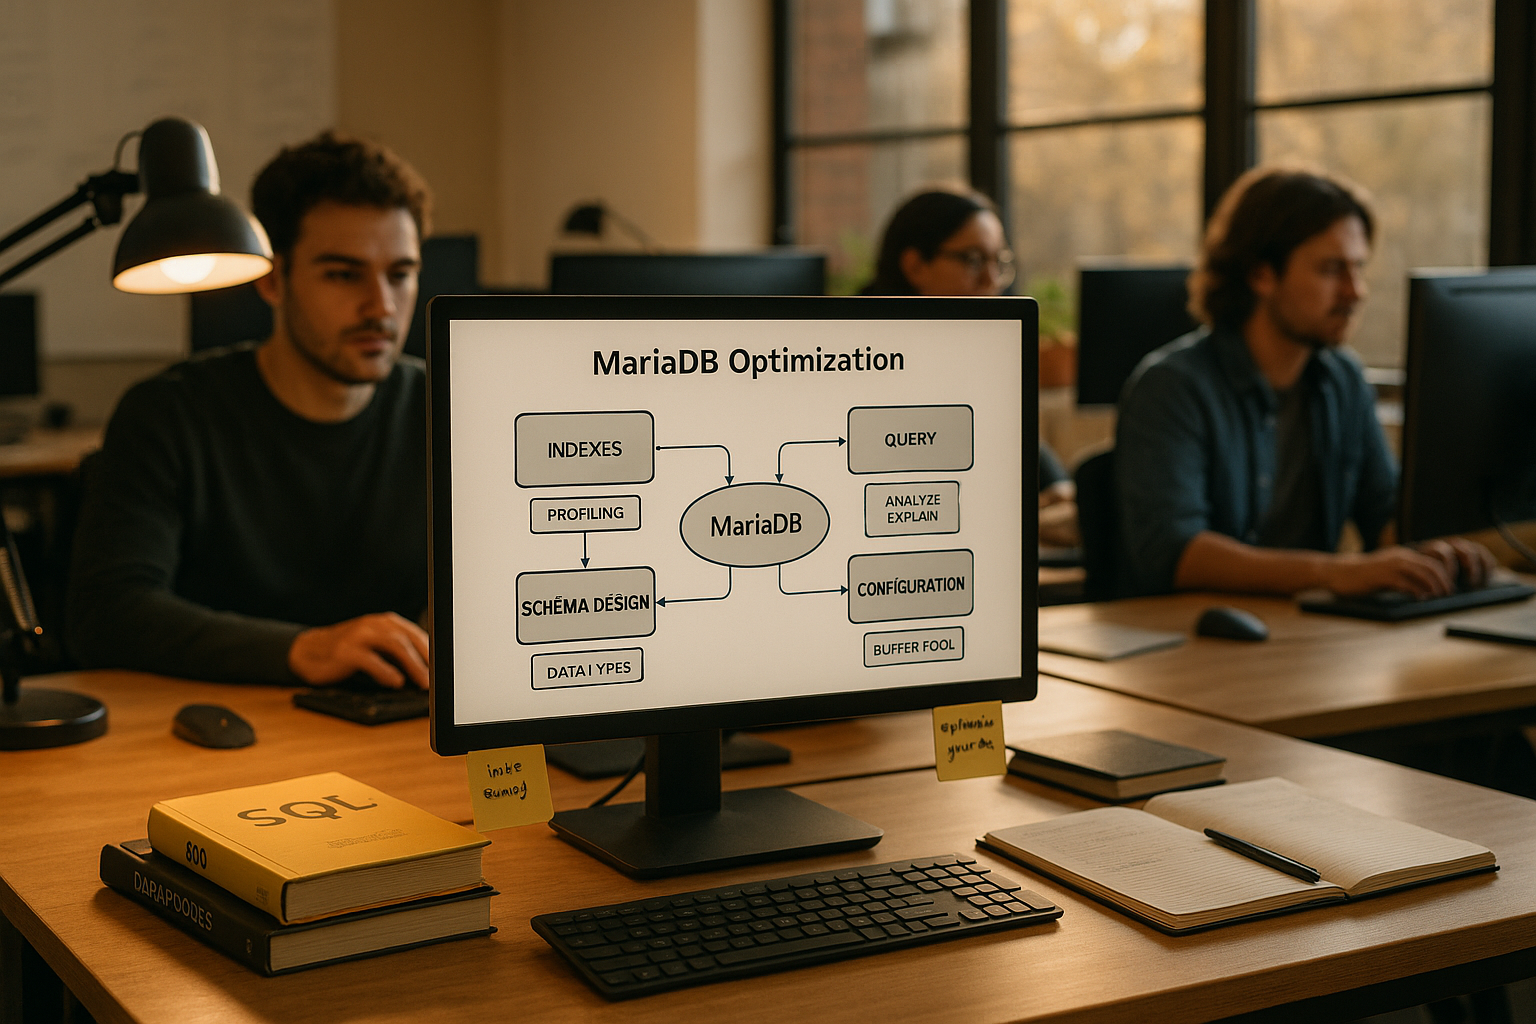
I enable dynamic logic via innodb_adaptive_flushing and help guide early warning behavior by innodb_adaptive_flushing_lwm. The fuller the redo log is and the faster it grows, the more aggressively InnoDB flushes to prevent a bottleneck. This rule ties the flush rate to the actual change throughput, which makes short I/O bursts less frequent. According to the MariaDB documentation, the intensity is based on checkpoint progress to avoid waiting times for disk write operations. I keep in mind that Adaptive Flushing distributes the workload but does not compensate for insufficient storage performance.
Understanding Key Metrics: Redo Log, Dirty Pages, and Checkpoints
First, I check the percentage fill level of the Redo Logs, the dirty page ratio in the buffer pool, and the checkpoint age. These three metrics tell me whether the server can flush early and consistently or whether work is piling up. If the checkpoint age increases too quickly, Adaptive Flushing kicks in, but I then also check the storage latency. For detailed questions about the I/O strategy, I find it helpful to look at the relevant Flush Methods, because they determine how efficiently the kernel processes write commands. I correlate these signals with the measured I/O capacity so that I can make targeted adjustments to the threshold values while ensuring the overall system remains consistent.
Adjusting the Adjustment Screws Correctly
I start with innodb_io_capacity and set the value close to the storage device's actual continuous power rating, not to theoretical maximums. For peaks, I consider innodb_io_capacity_max significantly higher, so that InnoDB can briefly ramp up under load without overloading the CPU. The threshold innodb_adaptive_flushing_lwm I configure it so that the server begins preflushing well before the redo log fills up. In addition, I set innodb_max_dirty_pages_pct_lwm so that InnoDB takes early corrective action as the dirty page ratio increases, preventing bottlenecks from occurring. I change only one parameter per cycle, meticulously log the results, and give the system time to go through several load phases before continuing with optimization.
Measuring I/O Capacity in Concrete Terms
I measure continuous write performance under production load because synthetic peak tests often raise false hopes, and the Uniformity obscure the picture. What’s meaningful are medium- to long-term averages and percentiles that withstand short-term smoothing. I look at write IOPS, write throughput, latencies, and the distribution of response times so that I’m not just looking at the average. If you base your assessment solely on the maximum value, you risk aggressive flush phases, while the actual transactions slow down. I draw conclusions for innodb_io_capacity based on long-term behavior observed over time, not on short-lived peak performances.
Overview of Initial Values and Thresholds
I use default values as a starting point, never as a rule set in stone, and test them against the actual workload, the size of the buffer pool, and the growth of the Redo Logs. SSD and NVMe systems clearly have higher values than HDDs, but I only set the rates high enough to ensure that read operations don't end up in the queue. For busy systems, I gradually scale up the capacity while monitoring latency, checkpoint age, and CPU usage together. If the dirty page ratio decreases steadily and the fluctuations in the redo log level subside, I’ve achieved a healthy safety margin. What remains critical for me is that I Tips control it, rather than overwriting it with excessive background I/O.
| Variable | Effect | Typical Initial Value for HDD | Typical Initial Value for SSD | Typical Initial Value for NVMe | What I pay attention to |
|---|---|---|---|---|---|
| innodb_adaptive_flushing | Enables dynamic flush | ON | ON | ON | Balancing Bursts |
| innodb_adaptive_flushing_lwm | Early Preflushing | 20–30% | 20-40% | 30–50% | Redo Log Level |
| innodb_io_capacity | Base Flush Rate | 100-300 | 800–2000 | 2000–8000 | Sustained Write IOPS |
| innodb_io_capacity_max | Emergency Threshold | 400–800 | 2000-6000 | 6000–20000 | Trim the tips |
| innodb_max_dirty_pages_pct_lwm | Dirty Page Low Water | 5–10% | 5–15% | 5–15% | Early corrective action |
Identifying Problem Cases and Symptoms
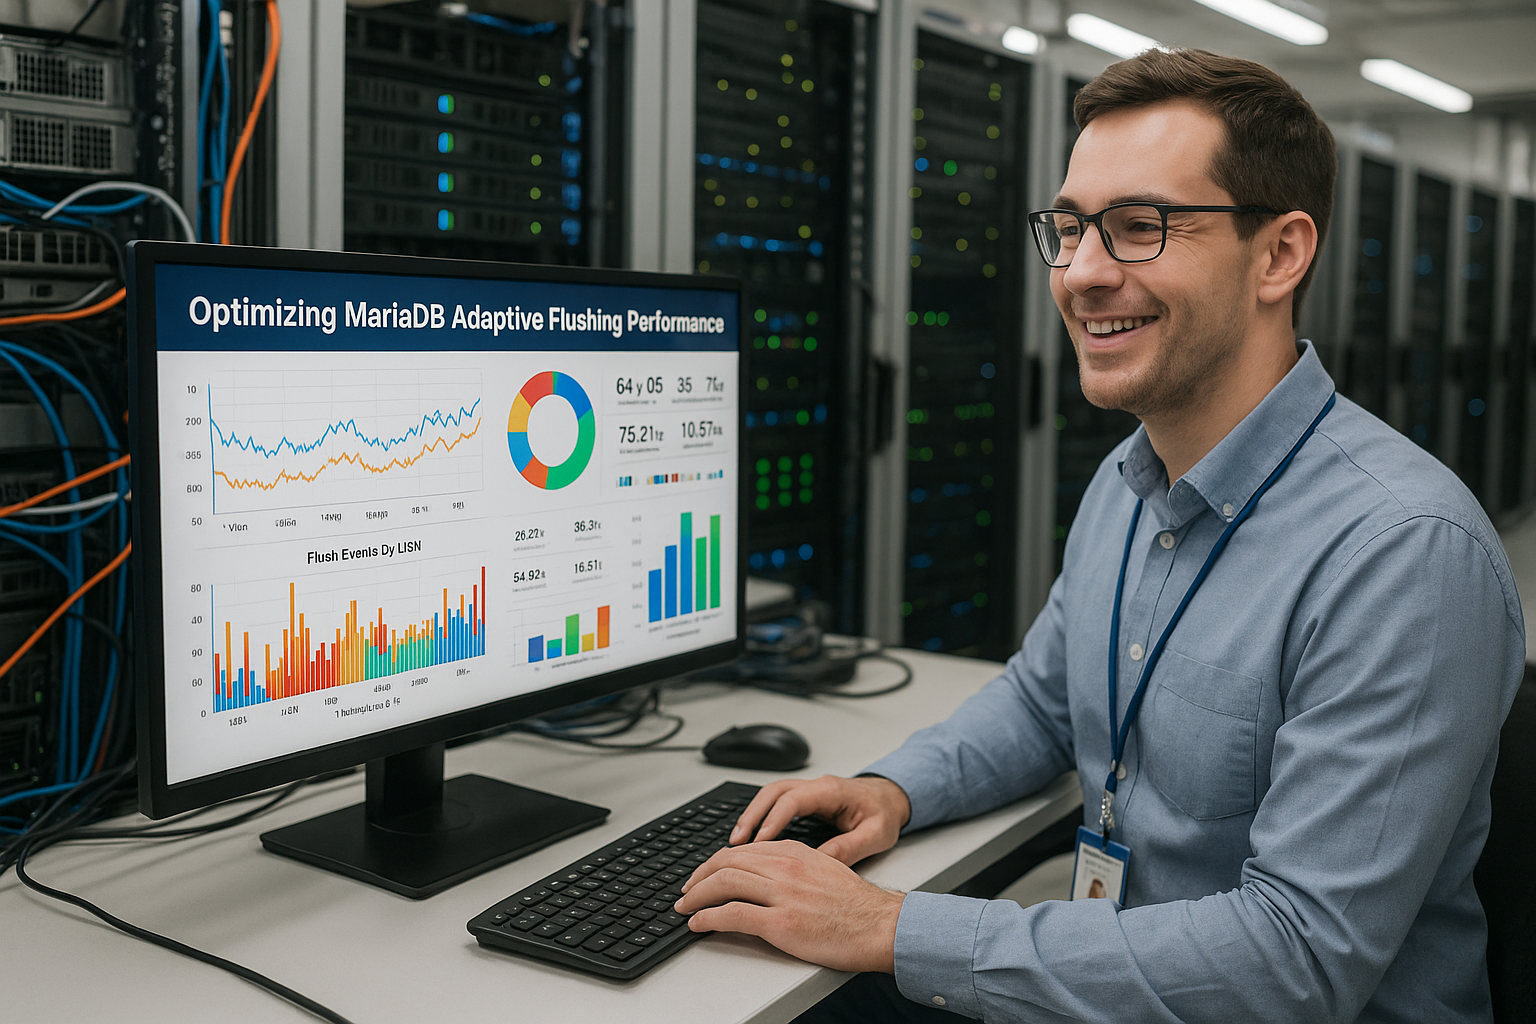
When I Flush-When I see spikes, I first check the I/O value: if it’s too low, dirty pages pile up and the system has to clean them up in a hurry. If the value is too high, background I/O overwhelms the live workload and forces reads into wait times. A sluggish checkpoint age that suddenly spikes tells me the server is responding too slowly. At the same time, a rapidly growing redo log level signals that the write side can’t keep up or that the log is undersized. I interpret these patterns together because a single number rarely fully explains the behavior of Adaptive Flushing.
Sizing the redo log for a uniform load
I select the size of the Redo Logs so that there is enough buffer for load spikes without checkpoints becoming too long. A larger log gives Adaptive Flushing more leeway to spread out the work, but I keep an eye on recovery times and storage budget. If the log is growing toward its limit by the second, a moderate increase eases the pressure and smooths out the flush curve. If increasing the log size doesn’t provide relief, the problem usually lies in inadequate I/O capacity or fluctuating storage latency. I decide whether to increase the log size again only after observing trends over a period of time, not based on snapshots.
Page Cleaner Threads and Concurrency
I'm looking at the number of page cleaner threads because they represent the parallel Flush-Control the performance of the buffer pool instances. Under heavy write loads, additional parallelism increases throughput, but I monitor the storage queue closely. If the storage device loses its effectiveness due to overfilled queues, I reduce the number of threads or limit the I/O capacity. For background information on this mechanism, I find the overview on Page Cleaner Threads, so that I can maintain a balance between pressure and fairness. I make pragmatic decisions: as many threads as necessary, but as few as makes sense, so that reads don't fall by the wayside.
Double-Write Buffer: Security vs. Write Speed
I take into account the Doublewrite-Buffer, because it protects against partial write errors but incurs additional I/O. On reliable NVMe systems, this extra overhead is less significant, while it’s more noticeable on slower storage. I measure the actual impact on latencies and the page flush rate before adjusting this setting. To make an informed decision, I refer to in-depth information on the Double-Write Buffer and see if a different risk and performance profile is a better fit. I never make a decision lightly, because data security and throughput are directly interrelated here.
Monitoring and Metrics in Practice
I evaluate the dirty page ratio, the ratio of flush rate to change rate, and the trend of the Checkpoint-Age. I also monitor the percentage utilization of the redo log over time, because a linear increase indicates that thresholds are being approached. I keep an eye on I/O latencies alongside the InnoDB statistics so that I can clearly identify cause and effect. After every parameter change, I compare identical load windows; otherwise, I’ll draw the wrong conclusions. I document the curves because a graph reveals more than a single data point, and this allows me to reliably identify breaks in trends.
Step-by-step tuning plan
I'll start with a realistic assessment of the Write rate and use that to set innodb_io_capacity. Then I define innodb_io_capacity_max as a fallback for high-pressure situations, leaving a sufficient margin relative to the base value. Next, I check `innodb_adaptive_flushing_lwm` and lower it if the checkpoint age is too high. Then I set `innodb_max_dirty_pages_pct_lwm` so that preflushing starts in time and peaks are reduced early. Finally, I adjust the redo log size, observe several load cycles again, and document every change before taking the next step.
Flush mechanism under the hood
I distinguish between two main motivations for writing: the Flush List Flushing (driven by progress at the checkpoint) and the LRU Flushing (driven by a lack of free pages). If the buffer pool fills up and there are no free pages, LRU flushing forces me to perform immediate writes, which causes latency spikes. Adaptive flushing aims to avoid these situations by continuously flushing the flush list. To ensure this works, I keep the proportion of free pages stable and monitor metrics such as LRU scan depth and the load per buffer pool instance. The more evenly the flush list is processed, the less often I have to wait for free pages in the foreground.
In doing so, I take into account the relationship between innodb_buffer_pool_instances, innodb_page_cleaners and the physical I/O capacity. More instances and cleaner threads increase parallelism, but only to the extent that the storage queues do not overflow. If flush operations reach high queue lengths, this is a sign that I should have flushed earlier and more slowly—this is exactly what I address using `innodb_adaptive_flushing_lwm` and the base/max capacities.
Transaction Commit, Redo, and Binlog in Context
I am examining commit paths and durability guarantees in the context of flush smoothing. innodb_flush_log_at_trx_commit and binlog synchronization affect how often the system performs fsyncs and the severity of short-term spikes. My guidelines:
- 1: Maximum durability (rewrites to disk with every commit). Safe, but requires frequent fsync operations and may be more erratic.
- 2: Redo is flushed every second; Commit only writes to the OS cache. This results in lower peak loads, but I run the risk of data loss in the event of an OS or host failure.
- 0: Similar to 2, but with even more aggressive caching. Use with caution on production systems.
Together with Binlog synchronization (sync_binlog) and Group Commit effects, I can bundle commits and reduce the number of hard synchronizations. It’s important that I don’t misuse these levers as a substitute for proper adaptive flushing tuning. I always evaluate risk, compliance requirements, and the desired latency profile together and make adjustments only to the extent permitted by business rules.
Purge Threads, History Length, and Long-Running Threads
I have the InnoDB Purge Note: A large number of deleted or updated lines generate undo data that is cleaned up asynchronously. If the History Length If this is too high, background overhead increases and competes with the page cleaners for I/O. This can indirectly slow down Adaptive Flushing. Solutions include setting an appropriate value for purge parallelism and avoiding long-running transactions that artificially keep the history open. I also plan batch operations so that I control the volume of redo and undo entries, rather than changing millions of rows in short bursts.
Change Buffer and Merge Phases
I take into account the Change Buffer during intensive secondary index updates. It reduces random I/O at runtime but shifts some of the work to later merge phases. These merges can generate additional flush load if they coincide with production peaks at inopportune times. I therefore monitor the size and activity of the change buffer, limit it as needed, and stagger bulk changes so that merge phases do not conflict with peak times. This keeps the flush rate more predictable and consistent.
Flush Methods and File System Factors
I make a conscious decision about the Flush Method and the file system options. O_DIRECT avoids duplicate caches and thus often smooths out write latencies, while AIO and Fsync paths have their own characteristics. I measure how these methods affect latency distribution and the stability of checkpoint progress, and for detailed questions, I refer to the notes on Flush Methods. In addition, I check file system mount options and maintenance routines (e.g., consistent TRIM/discard strategies for SSDs) to ensure that the underlying infrastructure does not introduce jitter without being noticed.
Diagnosis: Interpreting Status Messages Correctly
I'm moving SHOW ENGINE INNODB STATUS to assess checkpoint age and flush progress. From Log sequence number, Log flushed up to and Last checkpoint at I determine how large the gap is between generated and persisted changes. If the gap continues to grow faster than the redo log size allows, either my background flush is too slow or the I/O latency is too high. I compare these values with the InnoDB metrics for dirty pages, flush rate, and page cleaner activity so that I can make targeted adjustments rather than just treating the symptoms.
Operational Scenarios: Bulk, DDL, and Maintenance Windows
I am planning Bulk Loads and extensive DDL-Operations in such a way that Adaptive Flushing is not overridden. For scheduled maintenance windows, I temporarily increase innodb_io_capacity_max, ...to process pending writes in a controlled manner, and then lower it back to the normal level. During large imports, I moderate commit frequencies so that redo growth and checkpoint progress keep pace. Meanwhile, I continuously monitor the redo log fill level, dirty page ratio, and latency percentiles so that I can take immediate corrective action in case of deviations.
Common Misconceptions and Anti-Patterns
I won't fall into the trap, innodb_io_capacity_max as a permanent state. A max value that is too high can flood the memory queues and slow down real-time read operations. Nor do I „hide“ weak memory behind a huge redo log—larger logs smooth out I/O, but they don’t create I/O reserves. And I don’t simply accept latency spikes as a given: They’re often the result of preflushing that occurs too late or highly fluctuating background load, which I can mitigate by setting lower LWM thresholds and realistic capacity values. Finally, I avoid changing multiple tuning parameters at the same time; otherwise, I lose track of causality and cannot make improvements reproducible.
Briefly summarized
I use Adaptive Flushing to distribute I/O operations evenly over time and thus avoid latency spikes. The greatest impact comes from accurately setting `innodb_io_capacity` and maintaining a reasonable ratio to `innodb_io_capacity_max`. Setting early thresholds for redo log fill level and dirty page ratio helps me keep queues small. With appropriate redo logs, reasonable parallelism among the page cleaner threads, and vigilant monitoring, I can achieve more reliable write routines. According to the MariaDB documentation on system variables and page flushing, these tuning parameters work together—I adjust them incrementally and keep an eye on the effects until the system runs smoothly and predictably.


