Skip to content

The Linux cgroup CPU Controller controls how much computing time services, containers, and processes receive, and makes performance planning more precise. I’ll explain in detail how weighting, quotas, and best practices work together so you can allocate CPU time reliably and avoid bottlenecks.
Key points
- weighting versus Limit Understand: Fair Distribution or a Strict Cap
- cgroup v2 Prioritize: clear semantics, consistent hierarchy
- cpu.weight and cpu.max: the two control levers
- systemd Use: Set rules for each service
- Monitoring and Transparency: Reading cpu.stat and PSI
Understanding cgroups: Process Groups and Targets
I summarize processes in Groups together and use them to manage resources such as CPU, memory, and I/O within clearly defined hierarchies. Instead of juggling individual PIDs, I assign entire services, containers, or worker pools to a control group and set clear rules. This prevents a runaway task from slowing down the machine while critical components need to respond. This approach pays off especially in a hosting context, where many clients and services run on the same hardware. This article provides a good overview of how to implement this in practice: cgroups and Hosting, which makes the separation of loads easy to understand.
How the CPU Controller Works
The CPU controller divides computing time There are two mechanisms: relative weighting and absolute bandwidth limits. Weighting means that groups are allocated CPU shares relative to one another as soon as competition arises; groups with higher values then win time slices more frequently. A quota-based limit caps usage within a fixed time window, even when there is no competition. I choose weighting when fairness and dynamic utilization are the primary concerns, and I set quotas when a hard upper limit must remain fixed. The kernel documentation clearly illustrates this difference and shows how both mechanisms together form a coherent control model [1].
cgroup v1 vs. v2: Differences and Files
With cgroup v2 I manage CPU rules in a more consistent and organized way compared to the older v1 version. In v1, I used different files for each controller; in v2, I focus on `cpu.weight` for relative priority and `cpu.max` for a hard bandwidth limit. This clear separation reduces setup time, prevents misunderstandings, and simplifies audits. In hosting scenarios with many containers, the v2 hierarchy ensures transparent rules across all levels. An assessment of how this works in practice is provided in the article on cgroup v2 in Hosting, which addresses consistent control when hardware is shared.
| Topic | cgroup v1 | cgroup v2 | Typical Parameters |
|---|---|---|---|
| CPU Weighting | cpu.shares | cpu.weight | cpu.weight (The default is often 100) |
| CPU Quotas/Limits | cpu.cfs_quota_us + cpu.cfs_period_us | cpu.max | cpu.max (e.g., 20,000 100,000) |
| Hierarchy | Separate Controllers | Uniform Tree Structure | Common Rules for Each Level |
| Real time | Separate RT controller | Restrictions on RT | See the kernel notes [1] |
What matters to administrators is that Consistency I reduce errors in the configuration and ensure changes take effect more quickly. I document parameters on the group nodes so that everyone can see their current impact. When migrating from v1, I carefully check equivalents—especially “Shares” to “Weight” and “CFS Quota” to “cpu.max.” Only once test loads respond as expected do I move production services to the new hierarchy. This disciplined migration saves many support cycles down the line.
Hierarchy, Subtrees, and Delegation
In cgroup v2, I control controllers per level and delegate them as needed. Via cgroup.subtree_control I enable the CPU controller for child nodes; systemd usually handles this automatically when I set CPU properties. Important: In v2, I ideally keep processes in Leaf groups rather than intermediate nodes. This keeps the rules more unambiguous, and load balancing clearly follows the tree structure. In complex setups, I assign entire services to slices (e.g.,. tenant-a.slice), including services and worker pools. This clear separation makes it easier to delegate tasks to teams that work in „their“ subtrees without violating global policies.
Important parameters: cpu.weight and cpu.max
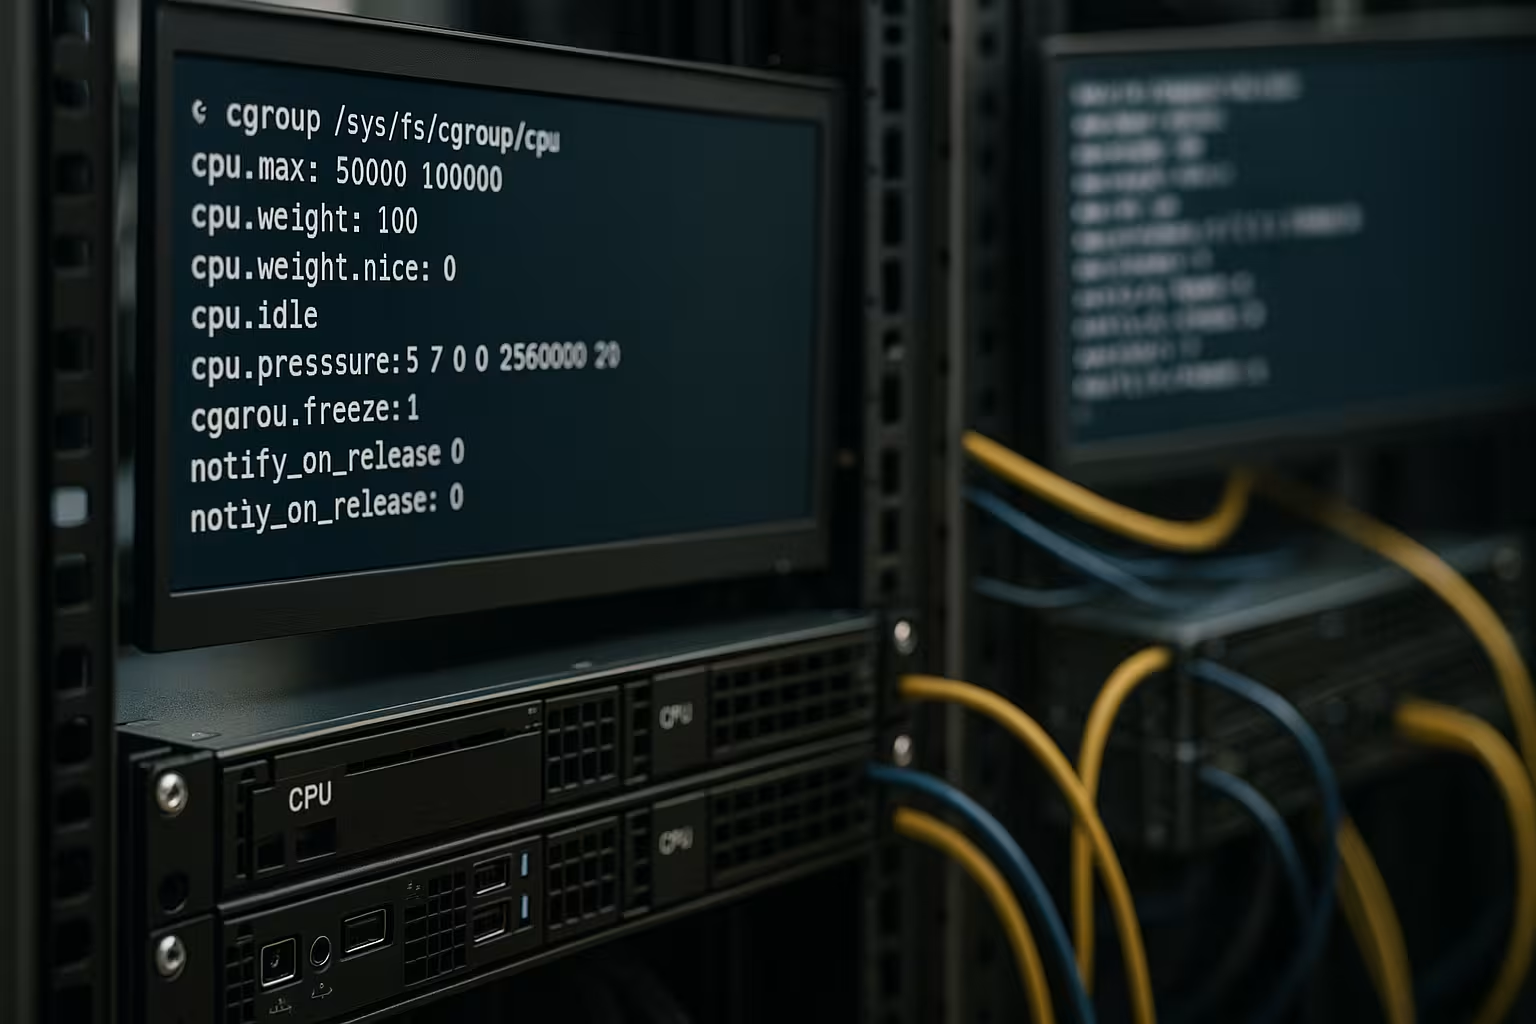
I use cpu.weight, to prioritize services relative to one another: If Service A is assigned a higher weight than Service B, A will receive CPU time more frequently under load. The default in v2 is often 100; higher values favor the respective group, but I stay within reasonable ranges to keep the balance manageable. For hard capping, I write in cpu.max a quota and a period, for example 20000 100000 for about 20 percent of a vCPU slot. With max First, I'll remove the cap, but leave the period in place, which simplifies diagnostics. Red Hat provides clear documentation on common settings and demonstrates their effects in a production environment [2].
Additional tuning parameters: cpu.weight.nice and UClamp
For teams that use the traditional nice-In terms of semantics, v2 offers cpu.weight.nice A practical bridge: I can help groups in the area of -20..19 rate, which is internally mapped to the weight scale. This ensures that relative expectations („prefer slightly,“ „reduce slightly“) remain consistent without having to specify exact weights each time. In addition, when necessary, I Utilization Clamping via cpu.uclamp.min and cpu.uclamp.max, ...to set a minimum or maximum limit for effective CPU utilization at the scheduler level. This ensures, for example, that a latency-critical service does not fall below the required baseline utilization even with a low number of threads, or that batch jobs do not receive an excessively high boost. This fine-tuning complements weighting and quotas, but does not replace them: I always test how UClamp interacts with my governor and power policies before rolling it out on a large scale.
Workload Scheduling: Fairness Versus Hard Limits
I consciously decide whether Fairness or strict upper limits take precedence. For latency-critical web services, I slightly increase their weight so that they are given priority when there is competition, without unduly disadvantaging other groups. For computationally intensive batch jobs, I also set a quota so they never take up too much time, even when the system is otherwise idle. I assign a moderate weight to databases and monitor the impact of checkpoints, rebuilds, or large queries; if necessary, I make temporary adjustments. I combine these rules with alerts so that I can respond early, before latency escalates.
Performance on Multicore Processors and Period Selection
A common stumbling block is the interpretation of Performance on Multicore Systems. A quota refers to the Total computation time for the group per period, not for individual cores. CPUQuota=200% or cpu.max = 200,000 100,000 This allows for roughly two CPU seconds per 100-millisecond period—distributed across all threads/cores. This can mean that many threads run in parallel for a short time until the group is „used up“ in the current period and is throttled. I avoid misunderstandings by always thinking of quotas in terms of „CPU slots“ and adjusting them to the service’s level of parallelism.
The standard period is often 100 ms. Shorter periods (z. B. (50 ms) allow throttling to take effect more quickly, but can cause micro-jitter; longer periods smooth things out, but respond more slowly. Under systemd, I adjust this with CPUQuotaPeriodSec= and verify whether latency peaks or throughput targets are better met. For interactive services, I measure end-to-end latency; for batch services, I focus on overall throughput and fairness toward neighbors.
Practical Application: Configuration with systemd and cgroup v2
With systemd, I set rules for each service because Service Files enable a reproducible configuration. With systemctl set-property I change them constantly, and I use drop-in files to version the settings neatly. Here's an example: systemctl set-property --runtime nginx.service CPUWeight=150 NGINX prioritizes lightly; systemctl set-property --runtime batch.service CPUQuota=20% caps batch jobs. I consistently enter /etc/systemd/system/service.d/limits.conf Set the appropriate options and reload the units. For a practical introduction, take a look at this guide to systemd Resource Control, which briefly summarizes the most common options.
# Examples for systemd v245+ with cgroup v2
# Relative Prioritization
systemctl set-property --runtime nginx.service CPUWeight=150

# Hard Upper Limit
systemctl set-property --runtime batch.service CPUQuota=20%

# Combination in a Drop-In File
mkdir -p /etc/systemd/system/php-fpm.service.d
cat < /etc/systemd/system/php-fpm.service.d/cpu.conf
[Service]
CPUWeight=120
CPUQuota=50%
EOF
systemctl daemon-reload
systemctl restart php-fpm.service
Slices for Tenants and Teams
For client or team boundaries, I use Slices as an organizational framework. A slice encapsulates multiple services and scopes that are managed collectively. This allows me to allocate budgets per customer without having to maintain each unit individually, and to delegate changes in a controlled manner.
# Tenant Slice with Default Rules
mkdir -p /etc/systemd/system/tenant-a.slice.d
cat < /etc/systemd/system/tenant-a.slice.d/cpu.conf
[Slice]
CPUWeight=120
CPUQuota=150%
# Optional: Period for finer-grained throttling
CPUQuotaPeriodSec=100ms
EOF
systemctl daemon-reload
systemctl restart tenant-a.slice
All services at tenant-a.slice inherit these settings. For short-term spikes, I temporarily increase the weight but keep the ratio stable so that neighboring systems aren't displaced.
Monitoring and troubleshooting
I check the effects and side effects using Transparency in metrics. The files cpu.stat and cpu.pressure (PSI) per cgroup gives me shares, wait times, and congestion figures that indicate throttling or overload. With top, htop and systemd-cgtop I identify distribution trends in real time and compare them with my rules. If latencies increase but the CPU is idle, the problem is more likely due to I/O or locks rather than CPU limits; in that case, I don’t rush to adjust the weighting. After making changes, I document the metrics over at least one load cycle to avoid false correlations.
Monitoring Playbook: What I'm Actually Reading
cpu.stat: usage_usec, user_usec, system_usec show consumption; nr_periods, throttled, throttled_usec expose severe throttling. Rises nr_throttled/nr_periods If the percentage is more than a few percent, the range is too narrow or the period is too short.cpu.pressure: I'm watching some avg 10/60/300 for latency-related bottlenecks. A consistently high value despite available CPUs indicates lock contention, affinity conflicts, or remote NUMA accesses.systemd-cgtopandP.S.: I'm checking whether threads can actually run in parallel or if they have to wait for exclusive resources.
To ensure reproducible tests, I use stress-ng, sysbench or use my own load generators and take metric snapshots before and after. I only roll out changes once the metrics consistently meet expectations.
Real Time and Special Features
At Real time-For workloads, I follow the guidelines in the kernel documentation, since v2 provides only limited support for the RT CPU controller. Certain RT threads must be in the root cgroup, and the configuration requires a careful approach. I also check how RT scheduling interacts with quotas to ensure that no deadline is unintentionally exceeded. For typical web and database services, I use standard policies because this setup remains more reliably predictable in everyday use. When I need RT, I clearly separate systems or reserve cores to prevent any unexpected interactions [1].
Fine-Tuning on Multi-Core Systems
The CPU controller divides Time window, not clock speed, so I combine it with cpuset and affinity as needed. For low-noise latency, I limit cross-socket switching, bind threads to NUMA-local cores, and optimize IRQ distribution. I allow batch services to run more flexibly so they can utilize spare capacity without blocking cores needed for critical frontends. I review turbo or power-saving policies because frequency changes can significantly alter behavior under load. Only the combination of quotas, weights, CPU affinity, and power strategy delivers consistent results.
SMT, NUMA, and Affinity in Practice
On systems with SMT/Hyper-Threading I note that two logical threads on a single physical core do not provide two full CPU slots. A ratio of „100 %“ covers one logical slot, not necessarily the full capacity of a physical core. I therefore measure latency and throughput with and without SMT enabled. On NUMA systems, I limit critical services with AllowedCPUs= (cpuset) or CPUAffinity= Use local cores and configure memory binding accordingly so that remote accesses don't ruin all the detailed planning.
Best Practices for Hosting and Containers
I start with moderate Defaults: Assign slightly higher weights to web services, keep databases close to the default, and set quotas for batch processing. For tenants, I set upper limits per customer and allow bursts via weighting, as long as there are no other demands. I document profiles by use case—such as „latency-critical,“ „mixed,“ and „computationally intensive“—and define clear ranges for `weight` and `cpu.max` for each profile. I first deploy changes to staging and test them with a synthetic load that realistically simulates peak conditions. I keep logs and metrics close to the cgroup boundaries so that diagnostics don’t get lost in the fog.
Container Orchestration: Shares, Requests, and Limits
In container environments I map Requests based on relative weighting and Limits strict quotas. This allows for bursts as long as nodes have free capacity and ensures fair distribution based on weight in competitive scenarios. Critical pods or services are given slightly more weight without the limits crowding out others. I make sure that the total limits per node are realistic given the available CPU; otherwise, despite well-defined rules, system-wide throttling will occur that affects all tenants.
Sample Configurations and Calculation Examples
I always calculate odds in Shares per vCPU slot: cpu.max = QUOTA PERIOD equals QUOTA/PERIOD of the slot. Example: 20000 100000 is 0.2 of a single CPU; across four CPUs, this amounts to a maximum of 0.8 total slots, but this distribution is not guaranteed. For percentage values under systemd, I write CPUQuota=20%, which, depending on the version, aligns with `cpu.max`. If you set hard limits, you’ll need to weigh burst behavior against latency: A period that’s too short can cause micro-stuttering, while a period that’s too long provides smoother distribution but responds more sluggishly. I therefore test periods between 50–100 ms and choose the option that best matches the service’s latency class [2].
Migration from v1 to v2 Without Any Surprises
When switching, I transfer cpu.shares in cpu.weight and cpu.cfs_quota_us/period_us in cpu.max. A pragmatic mapping for shares is: 1024 → ~100, 2048 → ~200, 512 → ~50. I make fine adjustments after load testing, because the scales differ. I also plan to include v2 rules for children cumulative Effect: A throttling quota at the parent node limits all subgroups collectively. That's why I often remove parent quotas (max) and make fine adjustments in the layers to avoid side effects.
Common Problems and Solutions
- 100 % confused with „all cores“: 100 % corresponds to one logical CPU slot, not the entire machine. Solution: Calculate the quota based on the number of slots required (e.g., 400 % for four slots).
- Period too short: Minor stuttering in interactive services. Solution: Increase the period or use weight instead of ratio.
- Weighting measured without competition: Weight only has an effect during competition. Solution: Run tests with a real parallel load.
- Forget about parental quotas: A limited parent restricts all children. Solution:
cpu.max=maxon the parent, limits on the leaves. - NUMA/socket ignored: Latency despite an idle CPU. Solution: Check affinity/CPU sets and memory locality.
Summary
With the CPU Controller I allocate computing time in a targeted manner, set fair priorities, and enforce strict limits where necessary. cgroup v2 provides clear parameters—such as `cpu.weight` and `cpu.max`—which I plan and measure based on the workload. Using systemd, I set rules for each service, verify their effectiveness with cpu.stat and PSI, and make adjustments without resorting to guesswork. For tenants, containers, and mixed server environments, this control remains key to achieving reliability and predictability. By documenting rules, introducing them step by step, and validating them with load tests, you can prevent bottlenecks and maintain control over CPU time.